KNOWLEDGE ARTICLE
What Is X-Robots-Tag?
HTTP indexing directives
Provides search engines with indexing and presentation directives through HTTP headers.
At a glance
X-Robots-Tag applies to HTML and resources such as PDFs and images without HTML meta tags. Common directives include noindex, nofollow and nosnippet.
Indexing controls beyond HTML
X-Robots-Tag sends indexing and presentation directives in an HTTP response. Depending on crawler support, these can include noindex, nofollow, nosnippet and other controls. It works for HTML, PDFs, images and documents without an HTML head, enabling server-level management.
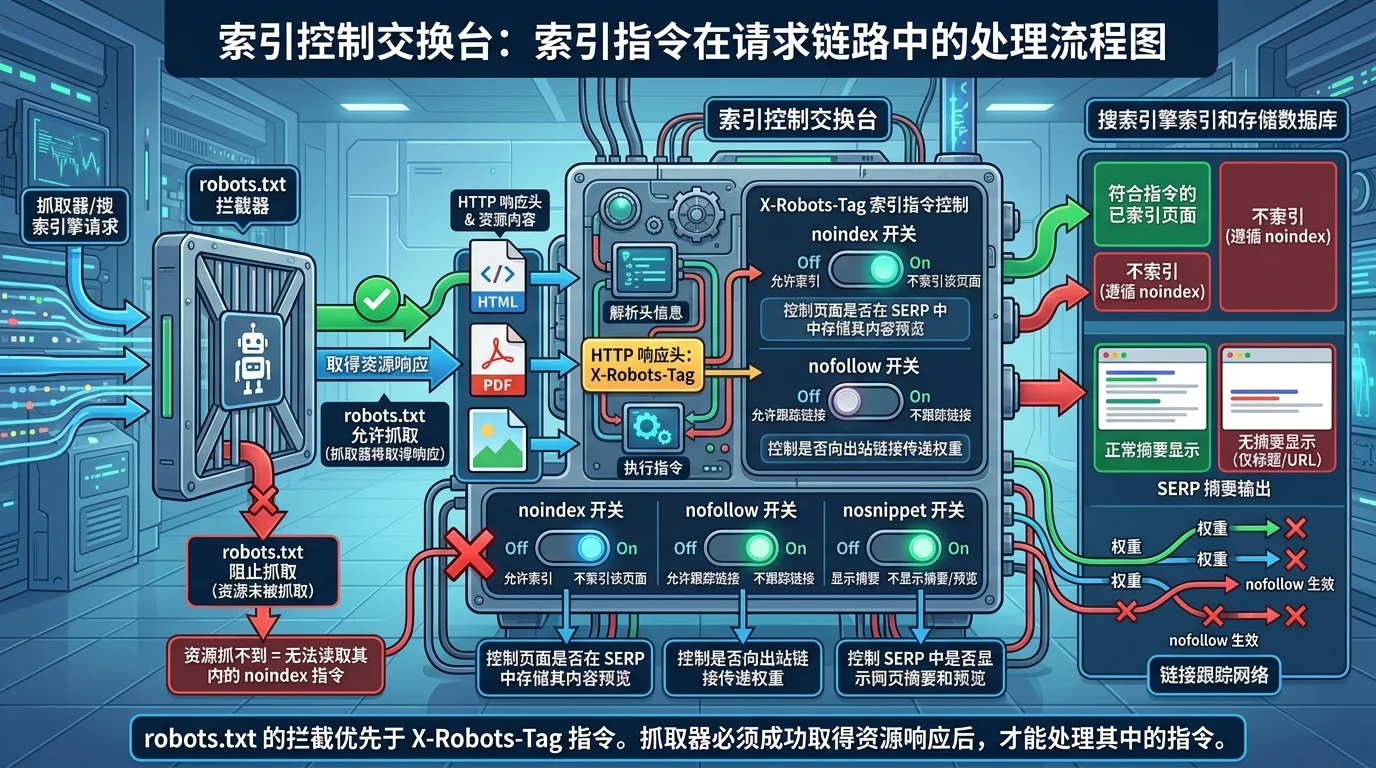
Headers can apply to supporting crawlers generally or use a particular user-agent prefix. Directives may be combined or returned on separate lines. Crawlers must fetch the resource to read them; a robots.txt block may prevent discovery of noindex.
Where crawlers read indexing instructions
- After requesting a URL, a crawler evaluates the response status, X-Robots-Tag and HTML meta robots to process indexing and presentation.
- Redirect intermediates and their final destinations may carry different instructions. The final crawlable resource and canonical signals are important to indexing decisions.
- Servers and CDNs can add headers by path, file type or environment. Overbroad rules may accidentally noindex an entire directory.
- Search platforms can retain an earlier state until recrawling. Removing noindex also requires a new crawl and reprocessing before recovery.
Why powerful bulk rules can affect the wrong content
Server rules can manage downloads, test environments, internal searches and export files without editing each page. Loose path matching in proxies, object storage or CDNs may also add noindex to public articles, images or sitemaps.
Test multiple resource types, statuses and hosts during release and monitor search reports. Keep access control separate: noindex asks search engines not to index; it does not protect confidential content from access.
Practical use and interpretation
An observed X-Robots-Tag can be displayed and its indexing or snippet implications explained. Whether the resource has already left search depends on crawler support, recrawling and other signals; a header does not prove an immediate result.
Absence on the homepage says nothing definitive about other resources. Inspect each intended resource; when its response is unavailable, the state remains unknown.
Points to consider
An unintended noindex can remove a resource from search, but a crawler must be able to fetch and recognize the directive.
Frequently asked questions
How does X-Robots-Tag differ from meta robots?
Their purposes are similar, but an HTTP header works for non-HTML resources and supports server-wide configuration.
Will noindex work if robots.txt blocks crawling?
A crawler that cannot fetch the resource may never see noindex. Removing a page from indexing generally requires letting the crawler retrieve the directive.
Does noindex protect private files?
No. It is an indexing instruction. Confidential resources require authentication and server access controls.