Website profiles · Technology insights · Alternatives

martinbarker.me No paid content found

Categories: Development

Seattle-based full-stack engineer, vinyl archivist and open-source contributor. Builds music digitization tools, Discogs utilities, and web apps for preserving and sharing music.

Visit website

Updated: 2026-10-02 03:45 Language: English (default) Access: Normal

Profile views 5 Outbound visits 0
Martin Barker Full homepage screenshot
Editorial Review

Website Review

What is Martin Barker?

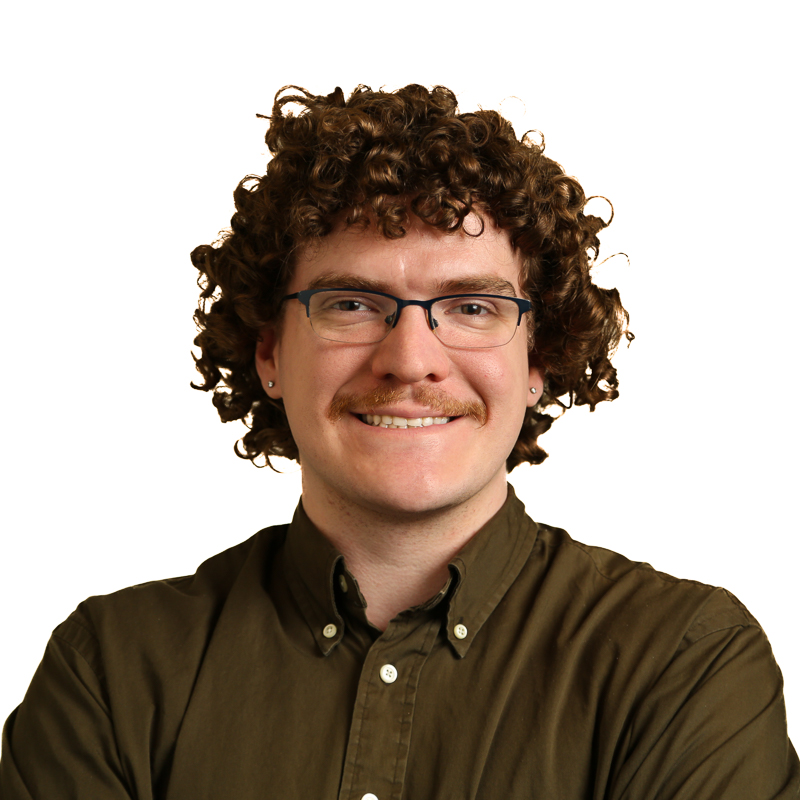
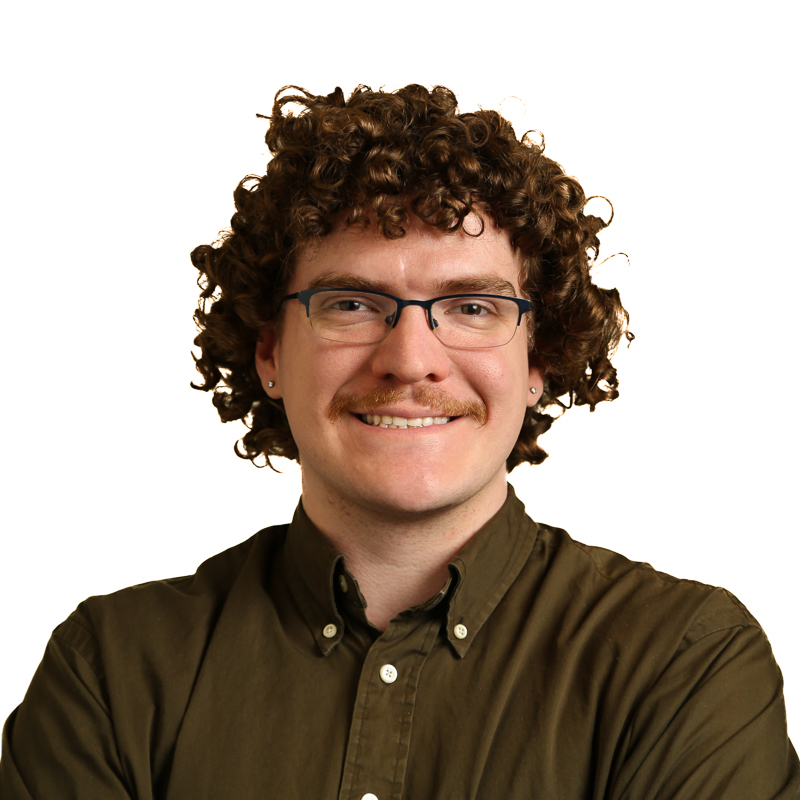
Martin Barker is a Seattle-based full-stack software developer, vinyl archivist and open-source contributor, according to Martin Barker. The site presents him as a working engineer who also builds free, open-source music applications, spanning music digitization tools, Discogs utilities and web apps for preserving and sharing music.

H3 What the page shows

  • Profession: Software Developer II at The Walt Disney Company in Seattle. His listed work covers leading a device lab, cross-platform testing infrastructure, internal tools built with Electron, React and Socket.IO, and Java-based end-to-end test suites.
  • Education: A Bachelor's in Applied Computer Science with a cybersecurity focus from Oregon State University, including coursework in Python, C++, C, web development (NodeJS, Django, HTML, CSS, JavaScript) and databases (SQL, PostgreSQL).
  • Side work: Open-source music software, described on the page as tools for music digitization and music preservation.

H3 Who this page is for If you are a developer curious about his open-source music tools, a recruiter checking his background, or someone into vinyl archiving looking for digitization utilities, the portfolio is aimed at you. Someone seeking a commercial product or paid service will not find one: the page frames the projects as free and open-source.

H3 A practical next step Decide what you need first. For hiring or collaboration, read the career and education sections for concrete stack and domain experience. For the music side, look at the listed projects and pick the one matching your task, for example a Discogs utility if you manage a collection, or a digitization tool if you are transferring vinyl. If you want to judge the code rather than the summary, the open-source repositories are the place to look.

What open-source music tools has Martin Barker built?

Martin Barker's portfolio presents him as a Seattle-based full-stack engineer, vinyl archivist and open-source contributor whose work centers on music preservation. The page groups his output into two broad categories: music digitization tools and Discogs utilities, alongside general web applications for preserving and sharing music. It describes this software as open-source and free, and points visitors to a sidebar listing of his projects rather than naming each one individually on the main page.

What the page confirms

  • Music digitization tools aimed at converting physical records into digital files.
  • Discogs utilities, presumably for cataloguing or managing record collections using Discogs data.
  • Web applications for preserving and sharing music.
  • All of it released as open source and free to use.

What it doesn't specify The evidence stops short of project names, repositories, licenses, supported formats or platforms. So if you arrive looking for a specific tool, the sidebar project list is the place to look, not the About section.

Who this is for The natural audience is people who collect vinyl or maintain large music libraries and want to digitize, tag or catalogue it without commercial software. A secondary audience is developers who want to read or contribute to the code. Someone with a shelf of records and a USB turntable is the clearest fit; someone wanting a polished consumer app with support may find an open-source project less predictable.

Practical next step Start with the project list and pick the tool matching your task: digitization if you're capturing audio, Discogs utilities if your problem is metadata and collection tracking. Check the repository's recent commit activity and open issues before committing your library to it, since small archival projects often depend on one maintainer's spare time.

For context on the data source these utilities likely build on, see Discogs. If you want to compare approaches to music library management more broadly, MusicBrainz is a useful reference point for open music metadata.

How can I digitize my vinyl records using Martin Barker's software?

Martin Barker's site describes him as a Seattle-based full-stack engineer and vinyl archivist who builds open-source music digitization tools and Discogs utilities, but the page itself is a portfolio: it names his background, education and Disney engineering roles, and points you to a project sidebar rather than documenting a step-by-step digitization workflow. So the practical answer is to go to that project list first, pick the tool that matches your goal, and read its own README or docs before touching your records.

Martin Barker

What to look for once you're there

  • A digitizer/recording tool — for capturing audio from a turntable into files. This is the piece that replaces a generic audio editor.
  • Discogs utilities — for cataloguing, matching releases, or filling in metadata. Useful if your collection is already listed on Discogs.
  • Web apps for preserving and sharing music — for playback, browsing or publishing a digitized collection rather than the raw capture step.

Match the tool to the job: capture, clean-up, metadata, and sharing are usually separate concerns, and a portfolio project may only cover one.

A realistic workflow

  1. Connect and test the chain first. Turntable → phono preamp (or a turntable with a built-in one) → USB audio interface or ADC → computer. Record a minute of a quiet groove and check the level meter; aim for peaks well below clipping, since vinyl surface noise and clicks eat headroom fast.
  2. Record at the highest rate you'll actually keep. Capture lossless, then export compressed copies later. Never record straight to MP3.
  3. Split and tag. One file per side is easier to record; one file per track is easier to use. Tag with artist, album, year, and pressing/catalogue number if you care about which version you have.
  4. Clean up conservatively. A light click-repair pass and a gentle high-pass filter are usually enough. Heavy noise reduction dulls cymbals and vocals, and it's irreversible once applied.
  5. Back up. Two copies, one off-site. A digitized collection that exists on one drive isn't preserved.

Choosing between his tools and a general-purpose alternative

Your priority Better fit
Discogs-centric cataloguing and metadata Barker's Discogs utilities
Simple capture with no scripting Any mature audio editor with a recording module
Automated, scriptable batch processing An open-source CLI tool, if his project offers one
Sharing an online collection His web apps, or a self-hosted music server

If you're digitizing a handful of records, a general audio editor will get you there with less setup. If you're working through hundreds of records and want metadata tied to Discogs, his tooling is aimed squarely at that problem.

Next step: open the sidebar project list, read the README for the digitization tool, and check its last commit date and open issues — an actively maintained project will tell you which audio formats and operating systems it actually supports before you commit your weekend to it.

What Discogs utilities does Martin Barker offer for organizing a record collection?

Martin Barker's portfolio describes him as a Seattle-based full-stack engineer and vinyl archivist who builds open-source music software, including Discogs utilities. However, the site content supplied here does not name or detail any specific Discogs tool—it only states that such utilities exist among his projects. So the honest answer is: Discogs-related utilities are listed as part of his work, but their exact features aren't described in the material available.

What this means for you

If you're trying to organize a record collection, a Discogs utility from a developer-archivist typically aims at one of a few jobs:

  • Collection export/import — pulling your Discogs collection data into a spreadsheet or local database so you can sort and filter it your own way.
  • Bulk editing — fixing or adding fields (condition, notes, tags) across many releases at once, which Discogs' own interface makes tedious.
  • Digitization workflows — linking physical records to digital files, tracklists or archive notes.

Which of these Martin's tools actually do, and how they compare to Discogs' own collection tools, isn't something this page evidence confirms.

Next step

Visit Martin Barker and open the projects list referenced in the sidebar to see the Discogs utilities directly. As a decision criterion: if you mainly need to browse and value your collection, Discogs' built-in tools are usually enough; if you need bulk edits, exports or a local archive tied to digitized audio, a dedicated utility is worth the setup time.

What is it like to work as a software developer at Disney's Seattle device lab?

The site describes Martin Barker's own role at The Walt Disney Company's Seattle device lab, so the clearest answer comes from his account: it is a hybrid of software engineering, hands-on hardware operations, and test infrastructure rather than a typical product-feature developer job.

What the role involves, per his experience notes

  • Device lab ownership: provisioning, inventory and day-to-day operations across a wide range of consumer devices.
  • Internal tooling: building device management and test orchestration tools with Electron, React and Socket.IO, including real-time device control.
  • Test automation: authoring and maintaining Cucumber/Gherkin suites in Java for behaviour-driven end-to-end testing, plus self-healing automation to cut flakiness in CI.
  • DevOps support: deployment automation, environment management and continuous integration/delivery.
  • Cross-team work: collaborating with QA to define and execute testing strategies across devices.

What that means in practice

A device lab is a physical fleet: phones, tablets, set-top boxes, consoles and similar hardware that must be charged, imaged, networked and tracked. The engineering problem is making that fleet reliably available to automated tests. So your day splits roughly between writing code (tooling, test frameworks, CI pipelines) and resolving physical or environmental problems — a device that drops off the network, an OS update that breaks a test, an inventory mismatch. The reward is leverage: one fix to a flaky suite can unblock many teams. The trade-off is that progress depends on hardware you do not fully control, and much of the work is internal and invisible to end users.

Who tends to do well here

  • Engineers comfortable with JavaScript/TypeScript front ends (React, Electron) and a JVM test stack (Java, Cucumber).
  • People who like CI/CD and reliability work more than shipping customer-facing features.
  • Anyone who enjoys debugging across layers — from a USB cable or Wi-Fi issue up to a failing pipeline.
  • Self-directed organisers, since inventory and provisioning are process-heavy.

Who might find it frustrating

  • Developers who want product ownership or design influence.
  • Those who prefer purely software problems with no physical component.
  • People who dislike maintaining test suites and chasing intermittent failures.

A practical next step

If you are considering this kind of role, take one flaky end-to-end test you already own and try to make it self-healing — for example, retry logic with state checks rather than fixed sleeps. That single exercise tells you whether the debugging-across-layers part energises or drains you. For background on the tooling patterns involved, the Electron, React and Cucumber documentation are the most direct references; Martin Barker's own project write-ups at Martin Barker show how he applies the same stack to music digitisation and Discogs utilities outside work.

How did Martin Barker's cybersecurity degree influence his software development career?

Martin Barker's cybersecurity focus at Oregon State University shows up less as a job title than as a working habit: he builds software with an eye for how systems fail, how devices are provisioned, and how tests can be trusted. His applied computer science degree, with a cybersecurity focus, gave him exposure to networking protocols, security, and threat detection alongside programming in Python, C++, C, bash, and Linux, plus web and database work in Node.js, Django, SQL, and PostgreSQL.

That mix maps directly onto his later work at The Walt Disney Company, where he has led a Seattle device lab and cross-platform testing infrastructure. The cybersecurity side is visible in concrete choices: owning device provisioning and inventory, building real-time device management tools with Electron, React, and Socket.IO, and writing Cucumber/Gherkin test suites in Java for behavior-driven end-to-end testing. His work on self-healing test automation to reduce flakiness is a reliability and risk-reduction practice as much as a testing one.

For a reader trying to judge the influence, look at where security thinking becomes engineering practice rather than a separate concern:

  • Provisioning and inventory — treating devices as managed assets with controlled access and lifecycle.
  • Threat-aware testing — using end-to-end suites to catch failures before they reach production.
  • DevOps and CI/CD — automating deployment and environment management so changes are repeatable and auditable.
  • Networking and Linux fluency — useful when debugging real-time tools and lab infrastructure.

A practical next step is to browse his open-source music tools on Martin Barker and look for how input handling, file permissions, and data preservation are treated in the code. That is where a cybersecurity background usually leaves the clearest fingerprints.

Related questions

More questions →
What Are Open-Source UI Element Libraries and How Do They Differ From UI Frameworks?

An open-source UI element library is a collection of individual, ready-made interface pieces—buttons, cards, inputs, toggles, loaders—that you copy into your own project and adapt. A UI framework, by contrast, is a structured system of components, conventions, and often a theming layer that governs how your whole interface is built. The practical difference: an element library gives you a snippet; a framework gives you a way of working. If you need a polished button in ten minutes, reach for the element library. If you're building a 40-screen product with a team, you probably want the framework.

What "open-source UI element library" actually means

The term gets used loosely, so it helps to separate the parts:

  • Open-source: the code is publicly available, and the license tells you what you may do with it—copy, modify, redistribute, or use commercially.
  • UI element: a single, self-contained piece of interface, usually small enough to read in one sitting. A button with hover states, a pricing card, a search field.
  • Library: a browsable, searchable collection of those elements, typically contributed by many different people.

On a site like Uiverse, elements are shared by a community and written in plain CSS or Tailwind. You find one you like, copy the markup and styles, paste them into your project, and adjust colors, spacing, and text to fit. There's no package to install and no build step required—which is exactly the appeal, and also the source of most of the confusion.

Element library vs. UI framework: the core differences

Dimension Open-source UI element library UI framework / design system
Unit of reuse A single snippet you copy A component you import or call
Installation None; paste into your code Package install, config, sometimes a provider
Consistency Depends on you; each element may look different Enforced by shared tokens and APIs
Theming Manual edits per element Central theme/config file
Updates You own the copy; no upstream updates Version bumps bring fixes and changes
Accessibility Varies per contributor; must be checked Usually tested and documented
Best for Prototypes, landing pages, small sites, one-off needs Multi-page apps, teams, long-lived products
Learning curve Low—read the CSS Higher—learn the API and conventions

The table isn't a verdict. It's a map of trade-offs. Element libraries win on speed and freedom; frameworks win on consistency and maintenance.

Licensing and attribution: what to check before you paste

This is where people get into trouble, and it's worth slowing down for.

  1. Find the license. Every element or collection should state one. Common open-source licenses include MIT, Apache-2.0, and BSD. Some projects use copyleft licenses like GPL, which can impose obligations if you redistribute your code.
  2. Understand what the license permits. MIT and Apache-2.0 are permissive: you can typically use the code in commercial and closed-source projects. Copyleft licenses may require you to release derivative source under the same terms.
  3. Check attribution requirements. Permissive licenses usually require you to keep the copyright notice and license text somewhere in your project. That's a real obligation, not a formality.
  4. Look for per-element terms. On community sites, the site's overall terms and the individual contributor's stated wishes may differ. If a contributor asks for credit, honor it.
  5. When in doubt, ask or avoid. If a snippet has no license at all, you don't have clear permission to reuse it. Treat "no license" as "not open source," even if the code is publicly visible.

This article is general information, not legal advice. For commercial products with real exposure, have someone qualified review the licenses you're relying on.

How to use a community element in your project: a practical workflow

Here's a repeatable process that avoids most of the usual mess.

1. Start from a real need, not a browsing session

Decide what you need first—"a compact primary button with a loading state"—then search. Browsing aimlessly produces a pile of pretty snippets that don't fit together.

2. Copy the smallest version that works

Take the markup and the styles. Strip anything you don't need: demo wrappers, extra animations, decorative layers. Less code means fewer surprises.

3. Convert it to your conventions

If your project uses design tokens or CSS variables, replace hard-coded values:

/* Before: hard-coded */
.button { background: #4f46e5; border-radius: 8px; }

/* After: token-based */
.button { background: var(--color-primary); border-radius: var(--radius-md); }

This one step is what keeps a copied element from looking like a foreign object in your UI.

4. Check accessibility before you ship

Community elements vary widely here. Verify at minimum:

  • Keyboard focus is visible and the element is reachable by Tab.
  • Color contrast meets WCAG AA (4.5:1 for normal text).
  • Interactive elements use semantic HTML (<button>, not a clickable <div>).
  • Form inputs have associated labels.
  • Motion respects prefers-reduced-motion.

5. Test in context

Paste it into a real page with real content. Long labels, small screens, and dark mode break more copied elements than anything else.

6. Note where it came from

Keep a short comment or an internal credits file: source, license, date. Future you—and your legal reviewer—will be grateful.

Where element libraries genuinely shine

  • Prototypes and demos: you need something clickable today, not a design system.
  • Landing pages and marketing sites: a handful of distinctive elements, each custom.
  • Filling gaps: your framework lacks one specific component, and you don't want to build it from scratch.
  • Learning: reading well-made CSS is one of the fastest ways to improve.
  • Small projects: a personal site doesn't need a theming architecture.

Where they fall short

  • Consistency at scale: ten elements from ten contributors rarely look like one product.
  • Maintenance: you own every copy. When your design changes, you edit each one.
  • Accessibility debt: you inherit whatever the contributor did or didn't do.
  • No upstream fixes: a bug fixed in the original won't reach your copy.
  • Integration friction: different naming conventions, different units, different assumptions about resets.

When to choose which

Choose an element library when the scope is small, the timeline is short, or you need a few distinctive pieces rather than a whole system.

Choose a framework or design system when multiple people build multiple screens over months, when consistency is a product requirement, or when accessibility and theming need to be guaranteed rather than checked.

A hybrid works well for many teams: adopt a framework for the structural components—forms, navigation, layout—and borrow individual elements for the places where you want personality. Just route every borrowed element through the same token and accessibility checks, so it lands as part of your system rather than beside it.

The short version: open-source UI element libraries are a fast, flexible way to get good-looking interface pieces into a project. They are not a substitute for a design system, and the license and accessibility details are the part worth reading carefully.

What Does "Open Source" Mean for a Zen Cart Online Store?

Open source means the software's source code is publicly available, so anyone can inspect, modify, and redistribute it. Zen Cart, the platform running this reptile supply store, is open-source e-commerce software: the store owner can read and change the code, and no license fee is paid to a vendor. That matters to a small shop because it removes per-sale or monthly software fees and allows deep customization — but it also means the owner (or a developer they hire) handles hosting, updates, and security. Note that "open source" here describes the store software, not the reptile foods and supplements sold on it.

Open source in plain terms

Proprietary store platforms typically charge a subscription or a percentage of sales and keep their code closed. Open-source platforms publish the code under a license that permits use and modification. In practice, for a store like this one:

  • No license fee. You pay for hosting and your own time, not for permission to run the software.
  • Full access to the code. Layouts, checkout flow, and product pages can be changed beyond what a theme editor allows.
  • Community development. Fixes and add-ons come from contributors and other store owners, not only from one company.

What it looks like on this store

The page evidence shows a typical Zen Cart storefront: category navigation (Bee Pollen, Cat Grass, Chia Seeds, Dandelion, Sprouting Seeds, Supplements), an "All Products" listing, reviews, and an information block with About Us, Shipping & Returns, Privacy Notice, Conditions of Use, Order Status, Site Map, Gift Certificate FAQ, and Discount Coupons. That structure — categories, reviews, coupons, gift certificates, order status — is what the platform provides out of the box. The store also publishes care guides (Russian Tortoise Care, Box Turtle Care, Redfoot Tortoise Care) and growing instructions, which are content pages the owner added rather than built-in store features.

Benefits for a small pet supply shop

  • Cost control. No platform subscription means a low fixed cost that doesn't scale with order volume.
  • Custom catalog logic. A shop selling seeds, dried weeds, and supplements by weight can adjust product options, units, and shipping rules directly in the code.
  • Content and commerce in one place. Care guides and growing instructions sit alongside the catalog, which supports the store's stated role of helping customers find foods for herbivore reptiles.
  • No vendor lock-in on data. You can export and migrate your catalog if you decide to move.

Trade-offs to plan for

Concern What it means in practice
Hosting You arrange your own web host and domain; the platform doesn't host the store for you
Security updates You apply patches yourself or pay someone to; skipping them is the main risk
Technical maintenance Theme changes, add-ons, and upgrades need someone comfortable with PHP-based code
Support Help comes from forums, documentation, and paid developers rather than a single support line
Add-on quality Third-party modules vary; test before relying on them for checkout or payments

Deciding whether it fits your store

Choose an open-source cart like Zen Cart if you want no license fees, need code-level customization, and have either technical skills or a developer you can call. Choose a hosted subscription platform instead if you'd rather not manage hosting, patches, and upgrades, and you're comfortable paying monthly for that convenience. A middle path works for many small shops: run the open-source cart on managed hosting that handles server updates, and keep a developer on retainer for store-level changes.

If you're evaluating this specific store as a model, the useful signal is that a niche reptile supply shop can run a full catalog, reviews, coupons, and care content on open-source software without a platform fee — the cost shifts from subscriptions to maintenance.

What Is the Seattle Scrabble Club and How Can I Play There?

The Seattle Scrabble Club is a NASPA-affiliated club (North American SCRABBLE® Players Association Club #253, Seattle) that normally meets every Thursday evening near Green Lake in Seattle, welcoming all levels from beginner to expert. However, the club is currently on hiatus — the last session was April 30, and the site notes the club is on hiatus as of May 2026 — so you cannot currently attend a regular session. Below is how the club works when active, so you can decide whether to plan for a future return.

Where and when the club meets

  • Location: Woodland Park Lawn Bowling Clubhouse (WPLBC), 6150 Whitman Ave N, Seattle, WA 98103. It sits just east of Aurora Ave N, between Woodland Park Zoo and Green Lake.
  • Day and time: Every Thursday. Games begin at 6:00 pm, so don't be late.
  • First-time arrival: Arrive by 5:55 pm if it's your first visit.
  • House rule: Silence your cell phone during play.

Cost and who can play

  • All levels welcome — beginner through expert.
  • First visit is always free.
  • Subsequent visits cost $10, collected during the first game.

Getting there

  • By bus: The Rapid Ride E line stops nearby, just off Aurora Ave N at N. 65th St and Woodland Pl. N.
  • By bike: Use the Green Lake bike path or West Green Lake Way North.
  • By car/navigation: Some navigation apps cannot find the clubhouse, so check the WPLBC website for maps and directions rather than relying on your app alone.

What to do before you go

Because the club is on hiatus, confirm current status before traveling. When active, the club points new players to two pages on its site:

  1. New Player Info — what to expect at a first club session.
  2. FAQs — details on the club and the broader North American club and tournament SCRABBLE® scene.

You can also follow club news and NASPA tournament updates through the site; it recently congratulated Alec Sjoholm and Nigel Peltier as 2025 NASPA champs.

Quick reference

Item Detail
Affiliation NASPA Club #253, Seattle
Meeting day Thursdays (currently on hiatus)
Start time 6:00 pm; first-timers by 5:55 pm
Venue Woodland Park Lawn Bowling Clubhouse, 6150 Whitman Ave N, Seattle, WA 98103
Cost First visit free; $10 per visit after
Levels Beginner to expert
Transit Rapid Ride E line, N. 65th St & Woodland Pl. N.

If you want to play once the club resumes, plan to arrive early on a Thursday, bring the $10 fee for any visit after your first, and check the New Player Info and FAQs pages beforehand. Until then, treat the club as inactive and watch the site for a restart announcement.

Website Overview

An established domain and managed infrastructure suggest continuity of operations and may support dependable delivery, although neither guarantees service quality.

Domain and Registration

Registered in 2017, this domain has about 8 years of history. That suggests continuity, although ownership and purpose may have changed. Transfer-protection status is present, helping reduce the risk of unauthorized domain transfers. The registrar is Gandi SAS, a widely used domain service provider. The domain uses the common .me extension, which is not an independent safety signal.

DNS and Email

Nameservers are provided by Cloudflare, indicating managed DNS hosting. No CNAME was found; the observed records resolve directly to addresses. No MX record was found. A conventional explicit inbound-mail route is not configured. DNSSEC signatures were not detected, so this additional DNS authenticity protection is not confirmed. The lowest observed DNS TTL is 300 seconds.

TLS and Certificates

The public key uses EC with 256 bits. The server supplied a complete certificate chain. No organization name is present in the certificate; the available fields are consistent with domain validation. The certificate was issued within the Google Trust Services cloud or CDN ecosystem. The certificate's total validity is about 90 days, consistent with a short renewal cycle.

HTTP and Browser Security

X-Powered-By exposes backend information: Next.js. The checked browser-security headers were not detected, leaving fewer explicit browser-side safeguards. The cf-ray response header indicates a CDN or caching proxy in the delivery path. No obvious internal addresses or debug information were found in the headers. The Server header identifies cloudflare without an exact version.

Technology Stack Analysis

The public page identifies Next.js, Cloudflare without precise versions, leaving fewer clues for version-specific scanning.

Search and Social Sharing

The meta description has 178 characters and may be shortened in search results. Twitter Card metadata is configured. The title has 44 characters, within a common display range. The observed directives allow indexing and link following. No Generator meta tag is publicly exposed.

Hosting and Email

DNSCloudflare
HostingCloudflare
EmailUnknown
Location Location unknown 104.21.40.186

User reviews (0)

  • No reviews yet.

Pages, Search and Sharing

Meta descriptionSeattle-based full-stack engineer, vinyl archivist and open-source contributor. Builds music digitization tools, Discogs utilities, and web apps for preserving and sharing music.
Canonical URLhttps://martinbarker.me
LanguageEnglish (default)
Twitter Cardsummary
All bots 0 allowed · 0 disallowed

Registration details RDAP / WHOIS

RegistrarGandi SAS
Registered2017-11-10
Expires2026-11-10
Domain statusclientTransferProhibited https://icann.org/epp#clientTransferProhibited
Nameserversbuck.ns.cloudflare.com、suzanne.ns.cloudflare.com
DNSSECunsigned

DNS records

TypeNameValueTTLPriority
Amartinbarker.me104.21.40.186300—
Amartinbarker.me172.67.156.75300—
AAAAmartinbarker.me2606:4700:3031::ac43:9c4b300—
AAAAmartinbarker.me2606:4700:3033::6815:28ba300—
NSmartinbarker.mebuck.ns.cloudflare.com86400—
NSmartinbarker.mesuzanne.ns.cloudflare.com86400—
TXTmartinbarker.meca3-c384f090e7924ead88a51a2278ab994b300—

TLS and certificates

AssessmentNormal configuration
Supported protocolsTLSv1.2、TLSv1.3
Negotiated protocolTLSv1.3
Certificate subjectmartinbarker.me
IssuerGoogle Trust Services
Valid until2026-11-13T03:20 · Remaining when checked: 41 days
Verification detailsCertificate trust: Passed · Hostname match: Passed

HTTP response headers

HeaderValue
content-typetext/html; charset=utf-8
cache-controls-maxage=31536000
servercloudflare

Identified technologies

Next.jsCloudflare