Website profiles · Technology insights · Alternatives

agentsky.dev

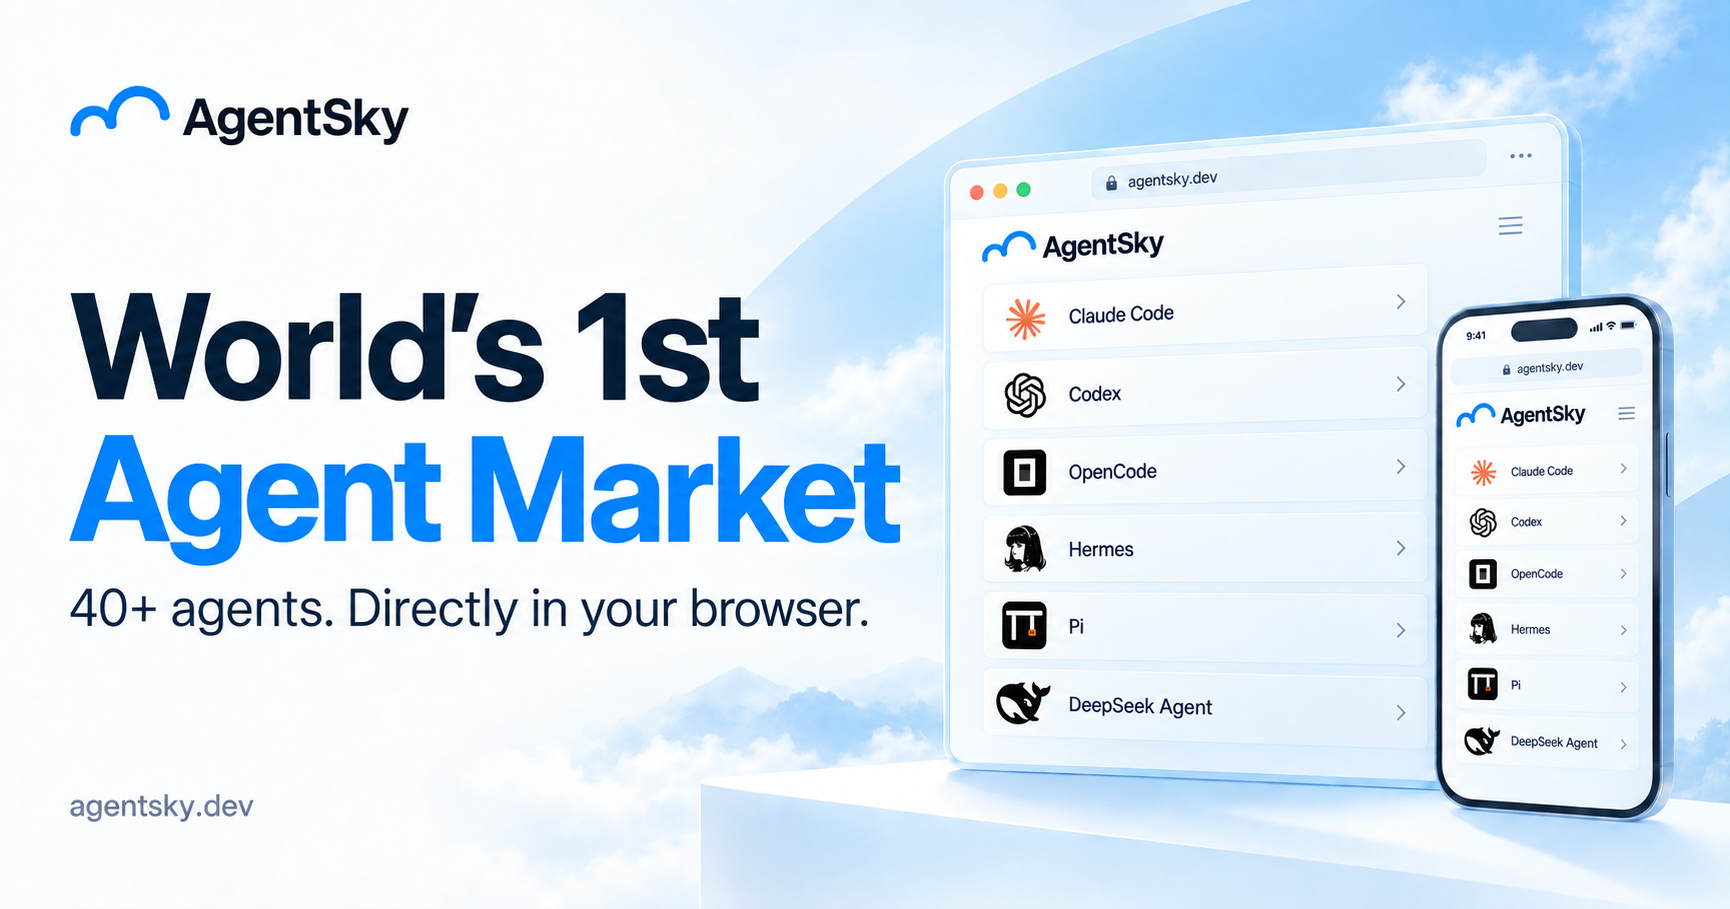
Use any agent, like Claude Code, Codex, Hermes and OpenCode, in your browser or through one API. Or ask your own agent to hire one.

Paid content
Visit website
Profile views 28 Outbound visits 50 Normal
AgentSky Full homepage screenshot

At a glance

Category
Development
Language
English
Paid-content signal
Paid contentObserved
Registered
2026
Hosting
CloudflareInferred
HTTPS certificate trusted
PassedObserved
Last updated

Website review

This review may include AI-generated content and is not individually verified. Domain, certificate and other facts come from the observed data on this page.

What is AgentSky?

AgentSky is a browser-based marketplace and gateway for AI agents. Rather than committing to a single assistant, you bring a task, run it against several agents, and pick whichever performs best. The site describes itself as letting you "test agents on your task, hire the winner," with access either in the browser, through a single API, or by having your own agent hire another one on your behalf.

What it actually offers

The catalog spans general-purpose assistants and coding agents. Named entries include Claude Code, Codex, Hermes, DeepSeek Harness, OpenClaw, pi, Kimi Code, opencode, Cline, Qwen Code, OpenHands, goose, Kilo, Gemini CLI, Mistral Vibe and Grok Build, alongside task-specific agents such as an Academic Paper Agent and an Ads Audit Agent. The page also lists connectors, models and tools as separate dimensions you can combine.

That mix points to two distinct audiences:

  • Developers who want to compare coding agents on a real repo or bug without installing each one locally.
  • Non-developers or teams who want a packaged agent for a defined job, like auditing ad campaigns or checking how visible a site is in AI search results.

How you'd use it

A practical scenario: you have a messy migration task. You paste the task, run it against three or four coding agents, and compare output quality, speed and cost before committing. The API route matters if you want that same routing inside your own product instead of a chat window.

The trade-off is the usual one for aggregators. You get breadth and side-by-side comparison in one place, but you're working through an intermediary layer rather than each vendor's native environment, and results depend on how faithfully each agent is wired up. If you only ever use one agent, going direct is simpler.

Next step

Start with one concrete task you already know the right answer to, run it across two or three agents, and judge on output quality first, then speed and cost. For pricing structure, see AgentSky. If you're weighing a specific coding agent, its own project page is the better source for capabilities: GitHub hosts most of the open-source ones listed.

How do I test multiple agents on my task and hire the winner?

AgentSky is built around exactly that workflow: run several agents against the same task, compare their output, then commit to the one that performed best. The page frames it as "Test agents on your task. Hire the winner," with a catalog of agents you can pick from and two access routes — browser or API.

How the comparison works in practice

Pick a task with a checkable result. Agent quality is easiest to judge when you can verify correctness rather than just read a plausible answer: a failing test suite to fix, a data file to clean, a research question with known sources, or a page whose content you can inspect.

Run the same prompt and the same inputs against each candidate, and keep everything else constant — same files, same tools, same time budget. Changing the task between runs tells you nothing about the agents.

Then judge on the dimensions that actually matter for your work:

  • Correctness — did it produce output you can use without repair?
  • Process — did it read the right files, run the right commands, avoid destructive moves?
  • Effort — how much prompting, correcting, or restarting did it take?
  • Cost and speed — acceptable for the value delivered?

Choosing which agents to test

The catalog spans general assistants and coding specialists, so a sensible shortlist mixes types rather than stacking five near-identical tools. For a coding task, pairing one broad assistant with two or three coding-focused agents gives a more informative spread than testing only coding agents. For research or content work, the general-purpose and research-oriented entries are the better comparison set.

Some agents connect to your own provider account rather than running on AgentSky's side, which matters if you already pay for a subscription and want usage to flow through it.

Browser or API

Route Best for Trade-off
Browser One-off comparisons, inspecting output by hand, quick trials Manual; hard to repeat consistently
API Repeated runs, scripted scoring, feeding results into your own pipeline Requires setup; overkill for a single decision

If you expect to re-run this comparison regularly — new models appear often — the API route pays off because you can script identical runs and score them the same way each time.

A practical next step

Write down your task, your pass/fail criterion, and a time limit before you start. Run three agents, score each against the criterion, and hire the winner for that task type. Keep the losing runs: knowing which agent failed and how is what tells you whether to re-test later. Related agent directories and comparison resources include GitHub for open-source agent projects and Hugging Face for model and agent listings.

Can I use AgentSky through an API instead of the browser?

Yes. AgentSky is positioned as a way to run agents either in the browser or through one API, so the API is a first-class option rather than an afterthought. The same catalog of agents is exposed both ways: the page lists browser access and API access as parallel routes, alongside connectors for letting an agent reach other tools.

What the API route looks like in practice

The listed agents span general-purpose assistants and coding agents — Hermes, Codex, Claude Code, opencode, Cline, Goose, Gemini CLI and others — so an API integration is mainly about choosing an agent per task rather than rebuilding your tooling around one vendor.

Approach Best for Trade-off
Browser Trying several agents on one task, comparing output by hand Manual, not scriptable
API Pipelines, scheduled jobs, embedding an agent in your own product You handle auth, retries and cost tracking
Connectors Letting an agent act on external services Setup and permission scoping

A practical reader scenario: a small team wants a nightly job that reviews pull requests. They point their CI at AgentSky's API, pick a coding agent, and keep the browser view for spot-checking results when a run looks wrong. The browser becomes the debugging surface, not the primary interface.

Next step

Check AgentSky for the API documentation and current plan details before committing. Decide on two criteria: whether you need per-task agent switching (the API's main advantage here) and whether your workload is interactive or batch — batch work is where the API pays off, while exploratory work is often faster in the browser. If you want to compare the underlying agents directly, GitHub hosts many of the open-source ones listed, such as opencode and Cline.

What is the difference between using an agent in the browser and hiring one through AgentSky's API?

Browser use is interactive and human-driven; API use is programmatic and agent-driven. AgentSky presents both as ways to reach the same catalog of agents, so the real difference is who or what is in the loop.

In the browser

You pick an agent from the market, give it a task, and watch or steer the work yourself. This suits evaluation: run the same job across several agents, compare outputs, then continue with the one that performed best. It is also the better fit for one-off tasks, exploratory work, and situations where you want to inspect intermediate steps before trusting the result. The trade-off is manual effort — every run needs a person to start it, judge it, and decide what happens next.

Through the API

Your own software calls an agent instead of a person clicking through a page. That makes sense when a task repeats, when it must run inside an existing pipeline, or when another agent should be able to request the work on its own. The page describes this as asking your own agent to hire one, which points to orchestration: your system decides when a task is worth delegating and which agent gets it. The trade-off is that you must handle inputs, outputs, failures, and cost control in code, and you lose the immediate visual oversight that browser use gives you.

Browser API
Who drives You Your software or another agent
Best for Trying agents, comparing results, one-off tasks Repeating tasks, pipelines, automated delegation
Oversight Direct, step by step Whatever logging and checks you build
Main cost Your time per run Engineering and integration work

How to choose

Start in the browser when the task is new or you do not yet know which agent handles it well. Move to the API once the task, the winning agent, and the expected output are stable enough that a machine can run it without you watching. Many teams do both: browser runs to select an agent, API calls to run it at scale.

A concrete example: a small team needs weekly competitor research. Week one, they run the same prompt through several research-capable agents in the browser and keep the one with the most reliable sourcing. From then on, a scheduled script calls that agent through the API and posts the result into their shared workspace, with a human reviewing only the final summary.

If you want to compare agents before committing, the market listing at AgentSky shows the available agents and their stated strengths, which is a reasonable starting point for a browser-side test.

How much does AgentSky cost?

AgentSky's own site lists a Pricing page, but the supplied page content doesn't state any figures, so the exact cost isn't something that can be quoted here. Treat pricing as a page to check rather than a number to assume.

What the page does tell you

  • There's a free entry point: the site shows "Log in" and "Sign up" alongside the ability to test agents in the browser or through the API.
  • The catalogue is broad — the page cites 64 agents, 55 models and 36 tools across categories like Code, Research, Finance and Data.
  • Some listed agents are third-party or community-built, and at least one ("Ads Audit Agent") is described as paid, which suggests pricing may vary by agent rather than being a single flat fee.
  • At least one entry, Gemini CLI, says it "Uses your own Gemini CLI account," implying you can bring an existing provider account instead of paying AgentSky for model usage.

A practical way to decide

If you're evaluating cost, separate two questions: what AgentSky charges for access, and what the underlying model or agent charges for work done. Bring-your-own-account agents can shift spend to a provider you already pay, while hosted agents likely fold usage into AgentSky's own billing.

As a concrete test, pick one real task — say, refactoring a small module — and run it through two or three coding agents from the market, then compare the reported usage. That gives you a per-task cost estimate instead of a headline price.

For current figures, start at the pricing page: AgentSky. If you want to compare against running agents locally or via a provider directly, GitHub hosts many of the open-source agents listed, such as opencode and goose.

Can I ask my own agent to hire another agent on AgentSky?

Yes. AgentSky is built around the idea that an agent can act as the buyer, not just the worker: the page states you can "ask your own agent to hire one." So instead of manually browsing the market and picking a tool, your existing agent can request another agent to handle a task.

What that looks like in practice

  • Your agent stays the orchestrator. It decides when a task is outside its strengths and delegates it.
  • AgentSky supplies the marketplace. The Market lists agents such as Claude Code, Codex, Hermes, OpenClaw, pi, opencode, Cline and Gemini CLI, each with a short description of what it is good at.
  • Access is consistent. You can reach agents in the browser or through one API, and the page also mentions connectors and a harness/model layer, which is what makes programmatic hiring plausible rather than purely manual.

A concrete scenario

Say you run a coding agent for your own repository. It can write and edit files, but you also need a competitive analysis with verified sources. Rather than switching tools yourself, your agent submits the task, AgentSky routes it to a research-oriented agent, and the result comes back into your workflow. The page's own framing — "Test agents on your task. Hire the winner." — suggests you can also run several agents against the same task and keep the best output.

Trade-offs to weigh

Approach Best when Cost
You pick the agent manually One-off tasks, you want direct control Your time, repeated each time
Your agent hires another Recurring or multi-step pipelines Less visibility into which agent ran; you need trust in routing

The main caveat is accountability: when your agent chooses the hire, you may not know which tool produced a given result unless the workflow logs it. Start with a single delegated task and check whether the returned output names the agent used and is reproducible before wiring it into anything recurring.

For pricing and access details, see AgentSky.

Related questions

More questions →
What Is OpenAPI-Generated API Documentation and How Does It Work?

OpenAPI-generated API documentation is reference documentation that is produced automatically from an OpenAPI description file rather than written by hand. You write (or generate) a machine-readable specification of your API — endpoints, parameters, request bodies, responses, schemas, and auth — and a documentation tool reads that file and renders a browsable, often interactive reference site. The spec becomes the single source of truth; the docs become a build artifact.

This differs from manually written docs in one fundamental way: with hand-written docs, the prose is the source of truth and the API is described separately. With spec-driven docs, the API description is the source, and every page, table, and code sample is derived from it.

How the workflow actually runs

A typical spec-driven documentation pipeline has five stages:

  1. Author or generate the spec. You either write an OpenAPI document by hand (YAML or JSON), or generate it from code annotations, framework metadata, or a design-first editor. Design-first means the spec is written before implementation; code-first means it is extracted from existing code.
  2. Validate and lint. The spec is checked against the OpenAPI schema and against style rules — consistent naming, required descriptions, no undocumented 4xx responses, no orphaned schemas.
  3. Bundle and transform. Multi-file specs are combined, $ref pointers are resolved, and the document is optionally split into per-tag or per-version outputs.
  4. Render. A documentation tool converts the spec into HTML: an endpoint list, a sidebar of operations, parameter tables, response schemas, and a "try it" console.
  5. Publish and version. The rendered site is deployed, and each API version gets its own snapshot so consumers can read docs matching the version they call.

Steps 2 through 5 are usually automated in CI. If the spec fails validation, the docs build fails — which is the point.

Spec-driven vs. hand-written documentation

Dimension OpenAPI-generated Hand-written
Source of truth The spec file The prose
Consistency with the API High, if the spec is accurate Drifts as the API changes
Effort per endpoint Low after setup Repeated for every endpoint
Narrative and tutorials Weak; needs separate pages Strong
Code samples Generated per language from schemas Written and maintained manually
Customization Bounded by the tool's templates Unlimited
Failure mode Accurate spec, poor docs, or stale spec Beautiful docs that describe an API that no longer exists

The practical conclusion most teams reach: generate the reference, write the guides. Reference material is repetitive and mechanical, which is exactly what generation is good at. Conceptual explanations, migration notes, and tutorials carry judgment that a spec cannot express.

What you get out of the box

Generated reference pages commonly include:

  • An operation list grouped by tag or path, with HTTP method and path.
  • Parameter tables showing name, location (path, query, header, cookie), type, required flag, and description.
  • Request and response schemas rendered as expandable trees, including nested objects and arrays.
  • Authentication details pulled from the securitySchemes section.
  • Interactive request consoles that let a reader send a real call from the browser.
  • Generated code samples in several languages, derived from the same schemas.
  • Multiple output formats, such as a static site, a single HTML file, or a mock server.

Because all of these come from one document, changing a field name in the spec updates the parameter table, the schema tree, and every code sample at once.

Where spec-driven documentation breaks down

Generation is not free. The trade-offs are real:

Spec quality becomes documentation quality. A field with no description produces a table row with an empty cell. A vague summary produces a vague heading. Tools can enforce presence of descriptions via linting, but they cannot enforce that the description is useful.

Customization has limits. If you need a page that does not map to an OpenAPI concept — a conceptual overview, a pricing explanation, a comparison of two endpoints — you write it outside the generator and link to it.

Not everything is expressible. Webhooks, streaming responses, long-polling behavior, and complex multi-step flows are awkward or impossible to describe fully in OpenAPI. Those need prose.

The spec can go stale. If the spec is maintained separately from the implementation, it drifts just like hand-written docs. The mitigation is to generate the spec from code, or to test the implementation against the spec in CI.

Interactive consoles need care. A "try it" button that hits a production API with real credentials is a security and rate-limit problem. Point it at a sandbox, or disable it.

Deciding whether to adopt it

Adopt spec-driven reference documentation if most of these are true:

  • Your API has more than a handful of endpoints, or changes frequently.
  • You ship client SDKs or code samples in more than one language.
  • Multiple teams consume the API and need a consistent, always-current reference.
  • You already have, or are willing to maintain, an OpenAPI description.

Stay with hand-written docs, or a hybrid, if:

  • Your API is small and stable, and the reference fits on one page.
  • Your documentation is mostly conceptual and contains little endpoint-level detail.
  • You cannot commit to keeping the spec in sync with the implementation.

A reasonable middle path: generate the reference from the spec, and hand-write the getting-started guide, authentication walkthrough, and error-handling page. Link the two directions so readers can move from concept to endpoint and back.

A minimal starting checklist

  1. Produce one valid OpenAPI document for a single API version.
  2. Add a linter with rules for descriptions, operation IDs, and error responses.
  3. Wire the docs build into CI so a failing spec fails the build.
  4. Render the reference and review it as a reader, not as the author.
  5. Write the two or three conceptual pages the generator cannot produce.
  6. Version the published docs alongside the API version.

The core idea is simple: describe the API once, in a format both machines and humans can read, and let the reference documentation fall out of that description. Everything else — tooling, hosting, interactivity — is a detail on top of that decision.

What Does a Postal Code API Return? Fields, Formats, and Common Use Cases

A postal code API returns structured location data for a given ZIP Code or Canadian postal code. A typical response includes the code itself, city, state or province, county, latitude/longitude, and — where available — ZIP+4 detail. More complete services add time zone, area codes, boundary geometry, and demographic fields. You send a code (or an address), and the API sends back a machine-readable record you can store, validate, or display.

This article explains what those responses contain, how requests are usually shaped, and where postal code data fits into real applications.

First, clear up the word "code"

The keyword "code" is overloaded, and that causes real confusion for developers:

  • Postal code — the ZIP Code (U.S.) or postal code (Canada) that identifies a delivery area.
  • API key — the credential you use to authenticate your requests. It is not postal data.
  • Source code — the program you write to call the API.

When someone searches for "postal code API code," they usually want example request/response code for a postal code service. The rest of this article treats it that way.

What a postal code API actually returns

Response fields vary by provider and endpoint, but the core set is fairly consistent. A single-code lookup commonly returns:

Field Example Notes
Postal code 90210 The code you queried
City Beverly Hills May be one of several acceptable place names
State / Province CA Two-letter abbreviation
County Los Angeles Useful for tax, territory, and reporting logic
Latitude / Longitude 34.0901, -118.4065 Usually the centroid of the area
ZIP+4 90210-1234 Present only when a specific delivery segment is known
Time zone America/Los_Angeles Helps with scheduling and display
Area codes 310, 424 Regional phone context

Richer datasets add 90+ fields: boundaries, population, income, elevation, and more. You rarely need all of them — request only what your application uses.

A representative JSON response

{
  "postal_code": "90210",
  "city": "Beverly Hills",
  "state": "CA",
  "county": "Los Angeles",
  "latitude": 34.0901,
  "longitude": -118.4065,
  "timezone": "America/Los_Angeles",
  "area_codes": ["310", "424"]
}

XML responses carry the same information in tag form. Choose based on what your stack parses most easily; JSON is the common default.

Common request patterns

Most postal code APIs support four patterns. Knowing which one you need prevents wasted calls.

1. Lookup by code

You have a code and want its details. This is the simplest and fastest call.

GET /lookup?code=90210

2. Reverse lookup by address

You have a street address and want to confirm or complete the code. This is the pattern behind checkout address validation.

GET /validate?street=...&city=...&state=...

3. Radius search

You have a center point and want all codes within a distance. Useful for store locators and delivery zones.

GET /radius?code=90210&miles=10

4. Batch validation

You have a file of addresses and want them cleaned in bulk. Batch endpoints trade latency for throughput and usually have their own limits.

Handling missing and ambiguous matches

Real data is messy. Plan for these cases:

  • No match — the code doesn't exist or the address is malformed. Return a clear error rather than a silent empty object.
  • Multiple matches — a city name may map to several codes, or a code may span several acceptable city names. Decide whether to pick the primary or return a list.
  • Partial match — the street is valid but the ZIP+4 isn't. Fall back to the 5-digit code.
  • Stale data — codes are added, retired, and reassigned. Refresh your dataset on a regular schedule.

A practical rule: validate at the point of entry, store the normalized result, and never re-derive it later from raw user input.

Practical use cases

  • Checkout address validation — catch typos before shipping, reduce failed deliveries.
  • Shipping zone lookup — map a code to a zone, carrier route, or rate table.
  • Data enrichment — append county, coordinates, or demographics to existing records.
  • Store and service locators — radius search to find nearby branches or coverage areas.
  • Territory and tax logic — county and boundary data drive jurisdiction rules.

Licensing and data-source considerations

Postal code data originates with national authorities — USPS in the United States and Canada Post in Canada. Providers license and repackage it, which is why accuracy, update frequency, and field coverage differ between services. Before committing:

  • Confirm the data source and how often it refreshes.
  • Check whether ZIP+4 and boundary data are included or sold separately.
  • Review usage limits and whether batch processing is allowed.
  • Read the license terms for redistribution and storage.

Pricing and plan details change, so check the provider's current documentation rather than relying on secondhand figures.

Getting started

  1. Decide which request pattern you need (lookup, reverse, radius, or batch).
  2. Pick the fields you'll actually store.
  3. Write a small test call and inspect the raw response.
  4. Add error handling for no-match and ambiguous cases.
  5. Cache results where the same codes repeat.

A postal code API is ultimately a translation layer: you give it a code or an address, and it gives back structured location facts. Understand the fields, match them to your use case, and handle the messy edges — that's most of the work.

What Are Open-Source UI Element Libraries and How Do They Differ From UI Frameworks?

An open-source UI element library is a collection of individual, ready-made interface pieces—buttons, cards, inputs, toggles, loaders—that you copy into your own project and adapt. A UI framework, by contrast, is a structured system of components, conventions, and often a theming layer that governs how your whole interface is built. The practical difference: an element library gives you a snippet; a framework gives you a way of working. If you need a polished button in ten minutes, reach for the element library. If you're building a 40-screen product with a team, you probably want the framework.

What "open-source UI element library" actually means

The term gets used loosely, so it helps to separate the parts:

  • Open-source: the code is publicly available, and the license tells you what you may do with it—copy, modify, redistribute, or use commercially.
  • UI element: a single, self-contained piece of interface, usually small enough to read in one sitting. A button with hover states, a pricing card, a search field.
  • Library: a browsable, searchable collection of those elements, typically contributed by many different people.

On a site like Uiverse, elements are shared by a community and written in plain CSS or Tailwind. You find one you like, copy the markup and styles, paste them into your project, and adjust colors, spacing, and text to fit. There's no package to install and no build step required—which is exactly the appeal, and also the source of most of the confusion.

Element library vs. UI framework: the core differences

Dimension Open-source UI element library UI framework / design system
Unit of reuse A single snippet you copy A component you import or call
Installation None; paste into your code Package install, config, sometimes a provider
Consistency Depends on you; each element may look different Enforced by shared tokens and APIs
Theming Manual edits per element Central theme/config file
Updates You own the copy; no upstream updates Version bumps bring fixes and changes
Accessibility Varies per contributor; must be checked Usually tested and documented
Best for Prototypes, landing pages, small sites, one-off needs Multi-page apps, teams, long-lived products
Learning curve Low—read the CSS Higher—learn the API and conventions

The table isn't a verdict. It's a map of trade-offs. Element libraries win on speed and freedom; frameworks win on consistency and maintenance.

Licensing and attribution: what to check before you paste

This is where people get into trouble, and it's worth slowing down for.

  1. Find the license. Every element or collection should state one. Common open-source licenses include MIT, Apache-2.0, and BSD. Some projects use copyleft licenses like GPL, which can impose obligations if you redistribute your code.
  2. Understand what the license permits. MIT and Apache-2.0 are permissive: you can typically use the code in commercial and closed-source projects. Copyleft licenses may require you to release derivative source under the same terms.
  3. Check attribution requirements. Permissive licenses usually require you to keep the copyright notice and license text somewhere in your project. That's a real obligation, not a formality.
  4. Look for per-element terms. On community sites, the site's overall terms and the individual contributor's stated wishes may differ. If a contributor asks for credit, honor it.
  5. When in doubt, ask or avoid. If a snippet has no license at all, you don't have clear permission to reuse it. Treat "no license" as "not open source," even if the code is publicly visible.

This article is general information, not legal advice. For commercial products with real exposure, have someone qualified review the licenses you're relying on.

How to use a community element in your project: a practical workflow

Here's a repeatable process that avoids most of the usual mess.

1. Start from a real need, not a browsing session

Decide what you need first—"a compact primary button with a loading state"—then search. Browsing aimlessly produces a pile of pretty snippets that don't fit together.

2. Copy the smallest version that works

Take the markup and the styles. Strip anything you don't need: demo wrappers, extra animations, decorative layers. Less code means fewer surprises.

3. Convert it to your conventions

If your project uses design tokens or CSS variables, replace hard-coded values:

/* Before: hard-coded */
.button { background: #4f46e5; border-radius: 8px; }

/* After: token-based */
.button { background: var(--color-primary); border-radius: var(--radius-md); }

This one step is what keeps a copied element from looking like a foreign object in your UI.

4. Check accessibility before you ship

Community elements vary widely here. Verify at minimum:

  • Keyboard focus is visible and the element is reachable by Tab.
  • Color contrast meets WCAG AA (4.5:1 for normal text).
  • Interactive elements use semantic HTML (<button>, not a clickable <div>).
  • Form inputs have associated labels.
  • Motion respects prefers-reduced-motion.

5. Test in context

Paste it into a real page with real content. Long labels, small screens, and dark mode break more copied elements than anything else.

6. Note where it came from

Keep a short comment or an internal credits file: source, license, date. Future you—and your legal reviewer—will be grateful.

Where element libraries genuinely shine

  • Prototypes and demos: you need something clickable today, not a design system.
  • Landing pages and marketing sites: a handful of distinctive elements, each custom.
  • Filling gaps: your framework lacks one specific component, and you don't want to build it from scratch.
  • Learning: reading well-made CSS is one of the fastest ways to improve.
  • Small projects: a personal site doesn't need a theming architecture.

Where they fall short

  • Consistency at scale: ten elements from ten contributors rarely look like one product.
  • Maintenance: you own every copy. When your design changes, you edit each one.
  • Accessibility debt: you inherit whatever the contributor did or didn't do.
  • No upstream fixes: a bug fixed in the original won't reach your copy.
  • Integration friction: different naming conventions, different units, different assumptions about resets.

When to choose which

Choose an element library when the scope is small, the timeline is short, or you need a few distinctive pieces rather than a whole system.

Choose a framework or design system when multiple people build multiple screens over months, when consistency is a product requirement, or when accessibility and theming need to be guaranteed rather than checked.

A hybrid works well for many teams: adopt a framework for the structural components—forms, navigation, layout—and borrow individual elements for the places where you want personality. Just route every borrowed element through the same token and accessibility checks, so it lands as part of your system rather than beside it.

The short version: open-source UI element libraries are a fast, flexible way to get good-looking interface pieces into a project. They are not a substitute for a design system, and the license and accessibility details are the part worth reading carefully.

Website Overview

Page metadata, canonical configuration and social previews work together to provide more consistent search and sharing presentation. An active inbound-mail setup with incomplete authentication may leave the domain more open to impersonation. Provider hosting alone does not close that gap.

Domain and Registration

The domain was registered less than a year ago and has limited historical evidence to assess. Transfer-protection status is present, helping reduce the risk of unauthorized domain transfers. The registrar is CloudFlare, Inc., a widely used domain service provider. The domain uses the common .dev extension, which is not an independent safety signal.

DNS and Email

The observed email authentication setup is incomplete: SPF is missing. Nameservers are provided by Cloudflare, indicating managed DNS hosting. MX records point to the Google Workspace email service. No CNAME was found; the observed records resolve directly to addresses. TXT records include verification markers for Google. Such markers may also remain after a service stops being used.

TLS and Certificates

The public key uses EC with 256 bits. The server supplied a complete certificate chain. No organization name is present in the certificate; the available fields are consistent with domain validation. The certificate was issued within the Google Trust Services cloud or CDN ecosystem. The certificate's total validity is about 90 days, consistent with a short renewal cycle.

HTTP and Browser Security

X-Powered-By exposes backend information: Next.js. The checked browser-security headers were not detected, leaving fewer explicit browser-side safeguards. The cf-ray response header indicates a CDN or caching proxy in the delivery path. No obvious internal addresses or debug information were found in the headers. The Server header identifies cloudflare without an exact version.

Technology Stack Analysis

The public page identifies Next.js, Google Analytics, Cloudflare without precise versions, leaving fewer clues for version-specific scanning.

Search and Social Sharing

Twitter Card metadata is configured. JSON-LD includes Organization data, helping describe the organization as an entity. The title has 24 characters, within a common display range. A meta description is present, with 131 characters. The observed directives allow indexing and link following.

Hosting and Email

DNSCloudflare
HostingCloudflare
EmailGoogle Workspace
Approximate IP geolocation (inferred; a CDN or proxy may differ from the origin server) Location unknown Inferred 104.21.58.6

Registration details

RDAP / WHOIS

RegistrarCloudFlare, Inc.
Registered2026-07-31
Expires2027-07-31
Domain statusclient transfer prohibited
Nameserversboyd.ns.cloudflare.com、donna.ns.cloudflare.com
DNSSECunsigned

DNS records

DNS

TypeNameValueTTLPriority
Aagentsky.dev104.21.58.6300—
Aagentsky.dev172.67.196.160300—
AAAAagentsky.dev2606:4700:3031::ac43:c4a0300—
AAAAagentsky.dev2606:4700:3037::6815:3a06300—
MXagentsky.devsmtp.google.com3001
NSagentsky.devboyd.ns.cloudflare.com86400—
NSagentsky.devdonna.ns.cloudflare.com86400—
TXTagentsky.devgoogle-site-verification=2Bv-ntp068Wv-Es8x4YS-HvQy4nUS5InBjllixnGTEY120—
TXTagentsky.devgoogle-site-verification=Dk3CPL2sz2k7DrZCn3nmSz1tAuDx4haMCrbWfpBtCis120—
TXTagentsky.devgoogle-site-verification=J_AE3i4C9pPrg8EYz35QZy6moVQBe7OAJH9k0_5wX0U120—
DMARC_dmarc.agentsky.devv=DMARC1; p=none; rua=mailto:[email protected]3600—

TLS and certificates

TLS / SSL

AssessmentNormal configuration
Supported protocolsTLSv1.2、TLSv1.3
Negotiated protocolTLSv1.3
Certificate subjectagentsky.dev
IssuerGoogle Trust Services
Valid until2026-12-27T03:10 · Remaining when checked: 80 days
Verification detailsCertificate trust: Passed · Hostname match: Passed

HTTP response headers

HTTP

HeaderValue
content-typetext/html; charset=utf-8
cache-controlprivate, no-cache, no-store, max-age=0, must-revalidate
servercloudflare

Identified technologies

Next.jsGoogle AnalyticsCloudflare

Pages, Search and Sharing

Meta descriptionUse any agent, like Claude Code, Codex, Hermes and OpenCode, in your browser or through one API. Or ask your own agent to hire one.
Canonical URLhttps://agentsky.dev
LanguageEnglish (default)
Twitter Cardsummary_large_image
All bots 1 allowed · 36 disallowed
  • Allow/
  • Disallow/admin$
  • Disallow/admin/
  • Disallow/admin?
  • Disallow/api/
  • Disallow/auth/
  • Disallow/billing$
  • Disallow/billing/
  • Disallow/billing?
  • Disallow/channels$
  • Disallow/channels/
  • Disallow/channels?
  • Disallow/connect$
  • Disallow/connect/
  • Disallow/connect?
  • Disallow/connectors$
  • Disallow/connectors/
  • Disallow/connectors?
  • Disallow/developer$
  • Disallow/developer/
  • Disallow/developer?
  • Disallow/library$
  • Disallow/library/
  • Disallow/library?
  • Disallow/playground/
  • Disallow/sessions$
  • Disallow/sessions/
  • Disallow/sessions?
  • Disallow/settings$
  • Disallow/settings/
  • Disallow/settings?
  • Disallow/skills$
  • Disallow/skills/
  • Disallow/skills?
  • Disallow/support$
  • Disallow/support/
  • Disallow/support?
gptbot 1 allowed · 36 disallowed
  • Allow/
  • Disallow/admin$
  • Disallow/admin/
  • Disallow/admin?
  • Disallow/api/
  • Disallow/auth/
  • Disallow/billing$
  • Disallow/billing/
  • Disallow/billing?
  • Disallow/channels$
  • Disallow/channels/
  • Disallow/channels?
  • Disallow/connect$
  • Disallow/connect/
  • Disallow/connect?
  • Disallow/connectors$
  • Disallow/connectors/
  • Disallow/connectors?
  • Disallow/developer$
  • Disallow/developer/
  • Disallow/developer?
  • Disallow/library$
  • Disallow/library/
  • Disallow/library?
  • Disallow/playground/
  • Disallow/sessions$
  • Disallow/sessions/
  • Disallow/sessions?
  • Disallow/settings$
  • Disallow/settings/
  • Disallow/settings?
  • Disallow/skills$
  • Disallow/skills/
  • Disallow/skills?
  • Disallow/support$
  • Disallow/support/
  • Disallow/support?
oai-searchbot 1 allowed · 36 disallowed
  • Allow/
  • Disallow/admin$
  • Disallow/admin/
  • Disallow/admin?
  • Disallow/api/
  • Disallow/auth/
  • Disallow/billing$
  • Disallow/billing/
  • Disallow/billing?
  • Disallow/channels$
  • Disallow/channels/
  • Disallow/channels?
  • Disallow/connect$
  • Disallow/connect/
  • Disallow/connect?
  • Disallow/connectors$
  • Disallow/connectors/
  • Disallow/connectors?
  • Disallow/developer$
  • Disallow/developer/
  • Disallow/developer?
  • Disallow/library$
  • Disallow/library/
  • Disallow/library?
  • Disallow/playground/
  • Disallow/sessions$
  • Disallow/sessions/
  • Disallow/sessions?
  • Disallow/settings$
  • Disallow/settings/
  • Disallow/settings?
  • Disallow/skills$
  • Disallow/skills/
  • Disallow/skills?
  • Disallow/support$
  • Disallow/support/
  • Disallow/support?
chatgpt-user 1 allowed · 36 disallowed
  • Allow/
  • Disallow/admin$
  • Disallow/admin/
  • Disallow/admin?
  • Disallow/api/
  • Disallow/auth/
  • Disallow/billing$
  • Disallow/billing/
  • Disallow/billing?
  • Disallow/channels$
  • Disallow/channels/
  • Disallow/channels?
  • Disallow/connect$
  • Disallow/connect/
  • Disallow/connect?
  • Disallow/connectors$
  • Disallow/connectors/
  • Disallow/connectors?
  • Disallow/developer$
  • Disallow/developer/
  • Disallow/developer?
  • Disallow/library$
  • Disallow/library/
  • Disallow/library?
  • Disallow/playground/
  • Disallow/sessions$
  • Disallow/sessions/
  • Disallow/sessions?
  • Disallow/settings$
  • Disallow/settings/
  • Disallow/settings?
  • Disallow/skills$
  • Disallow/skills/
  • Disallow/skills?
  • Disallow/support$
  • Disallow/support/
  • Disallow/support?
claudebot 1 allowed · 36 disallowed
  • Allow/
  • Disallow/admin$
  • Disallow/admin/
  • Disallow/admin?
  • Disallow/api/
  • Disallow/auth/
  • Disallow/billing$
  • Disallow/billing/
  • Disallow/billing?
  • Disallow/channels$
  • Disallow/channels/
  • Disallow/channels?
  • Disallow/connect$
  • Disallow/connect/
  • Disallow/connect?
  • Disallow/connectors$
  • Disallow/connectors/
  • Disallow/connectors?
  • Disallow/developer$
  • Disallow/developer/
  • Disallow/developer?
  • Disallow/library$
  • Disallow/library/
  • Disallow/library?
  • Disallow/playground/
  • Disallow/sessions$
  • Disallow/sessions/
  • Disallow/sessions?
  • Disallow/settings$
  • Disallow/settings/
  • Disallow/settings?
  • Disallow/skills$
  • Disallow/skills/
  • Disallow/skills?
  • Disallow/support$
  • Disallow/support/
  • Disallow/support?
anthropic-ai 1 allowed · 36 disallowed
  • Allow/
  • Disallow/admin$
  • Disallow/admin/
  • Disallow/admin?
  • Disallow/api/
  • Disallow/auth/
  • Disallow/billing$
  • Disallow/billing/
  • Disallow/billing?
  • Disallow/channels$
  • Disallow/channels/
  • Disallow/channels?
  • Disallow/connect$
  • Disallow/connect/
  • Disallow/connect?
  • Disallow/connectors$
  • Disallow/connectors/
  • Disallow/connectors?
  • Disallow/developer$
  • Disallow/developer/
  • Disallow/developer?
  • Disallow/library$
  • Disallow/library/
  • Disallow/library?
  • Disallow/playground/
  • Disallow/sessions$
  • Disallow/sessions/
  • Disallow/sessions?
  • Disallow/settings$
  • Disallow/settings/
  • Disallow/settings?
  • Disallow/skills$
  • Disallow/skills/
  • Disallow/skills?
  • Disallow/support$
  • Disallow/support/
  • Disallow/support?
claude-web 1 allowed · 36 disallowed
  • Allow/
  • Disallow/admin$
  • Disallow/admin/
  • Disallow/admin?
  • Disallow/api/
  • Disallow/auth/
  • Disallow/billing$
  • Disallow/billing/
  • Disallow/billing?
  • Disallow/channels$
  • Disallow/channels/
  • Disallow/channels?
  • Disallow/connect$
  • Disallow/connect/
  • Disallow/connect?
  • Disallow/connectors$
  • Disallow/connectors/
  • Disallow/connectors?
  • Disallow/developer$
  • Disallow/developer/
  • Disallow/developer?
  • Disallow/library$
  • Disallow/library/
  • Disallow/library?
  • Disallow/playground/
  • Disallow/sessions$
  • Disallow/sessions/
  • Disallow/sessions?
  • Disallow/settings$
  • Disallow/settings/
  • Disallow/settings?
  • Disallow/skills$
  • Disallow/skills/
  • Disallow/skills?
  • Disallow/support$
  • Disallow/support/
  • Disallow/support?
perplexitybot 1 allowed · 36 disallowed
  • Allow/
  • Disallow/admin$
  • Disallow/admin/
  • Disallow/admin?
  • Disallow/api/
  • Disallow/auth/
  • Disallow/billing$
  • Disallow/billing/
  • Disallow/billing?
  • Disallow/channels$
  • Disallow/channels/
  • Disallow/channels?
  • Disallow/connect$
  • Disallow/connect/
  • Disallow/connect?
  • Disallow/connectors$
  • Disallow/connectors/
  • Disallow/connectors?
  • Disallow/developer$
  • Disallow/developer/
  • Disallow/developer?
  • Disallow/library$
  • Disallow/library/
  • Disallow/library?
  • Disallow/playground/
  • Disallow/sessions$
  • Disallow/sessions/
  • Disallow/sessions?
  • Disallow/settings$
  • Disallow/settings/
  • Disallow/settings?
  • Disallow/skills$
  • Disallow/skills/
  • Disallow/skills?
  • Disallow/support$
  • Disallow/support/
  • Disallow/support?
google-extended 1 allowed · 36 disallowed
  • Allow/
  • Disallow/admin$
  • Disallow/admin/
  • Disallow/admin?
  • Disallow/api/
  • Disallow/auth/
  • Disallow/billing$
  • Disallow/billing/
  • Disallow/billing?
  • Disallow/channels$
  • Disallow/channels/
  • Disallow/channels?
  • Disallow/connect$
  • Disallow/connect/
  • Disallow/connect?
  • Disallow/connectors$
  • Disallow/connectors/
  • Disallow/connectors?
  • Disallow/developer$
  • Disallow/developer/
  • Disallow/developer?
  • Disallow/library$
  • Disallow/library/
  • Disallow/library?
  • Disallow/playground/
  • Disallow/sessions$
  • Disallow/sessions/
  • Disallow/sessions?
  • Disallow/settings$
  • Disallow/settings/
  • Disallow/settings?
  • Disallow/skills$
  • Disallow/skills/
  • Disallow/skills?
  • Disallow/support$
  • Disallow/support/
  • Disallow/support?
ccbot 1 allowed · 36 disallowed
  • Allow/
  • Disallow/admin$
  • Disallow/admin/
  • Disallow/admin?
  • Disallow/api/
  • Disallow/auth/
  • Disallow/billing$
  • Disallow/billing/
  • Disallow/billing?
  • Disallow/channels$
  • Disallow/channels/
  • Disallow/channels?
  • Disallow/connect$
  • Disallow/connect/
  • Disallow/connect?
  • Disallow/connectors$
  • Disallow/connectors/
  • Disallow/connectors?
  • Disallow/developer$
  • Disallow/developer/
  • Disallow/developer?
  • Disallow/library$
  • Disallow/library/
  • Disallow/library?
  • Disallow/playground/
  • Disallow/sessions$
  • Disallow/sessions/
  • Disallow/sessions?
  • Disallow/settings$
  • Disallow/settings/
  • Disallow/settings?
  • Disallow/skills$
  • Disallow/skills/
  • Disallow/skills?
  • Disallow/support$
  • Disallow/support/
  • Disallow/support?

User reviews (0)

  • No reviews yet.